CoreWeave makes Nvidia Vera Rubin NVL72 available, with Cognition as first production customer
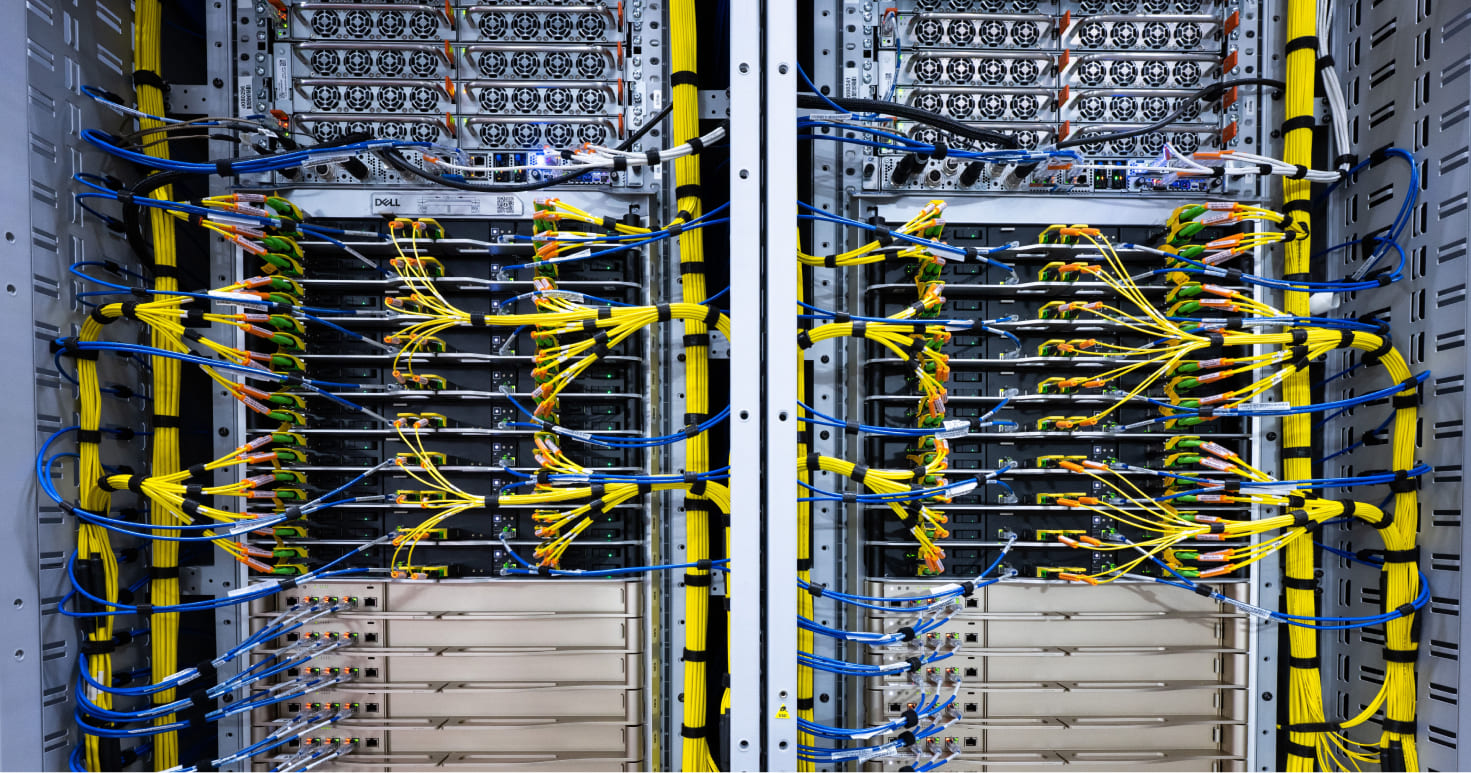
Cognition reports up to 4.8x total token throughput versus GB200 NVL72 on its SWE-2 inference workload; figures are company-measured.
Cognition reports up to 4.8x total token throughput versus GB200 NVL72 on its SWE-2 inference workload; figures are company-measured.