OpenAI and Ligo launch BioBasicsBench for wet-lab AI agents
Unite.AI summarises OpenAI’s Nov 6 post: 100 raw-data tasks; at xhigh, GPT-6 Astra scored 66.7% mean reward versus 43.8% for GPT-5.6 Sol.
Why it matters
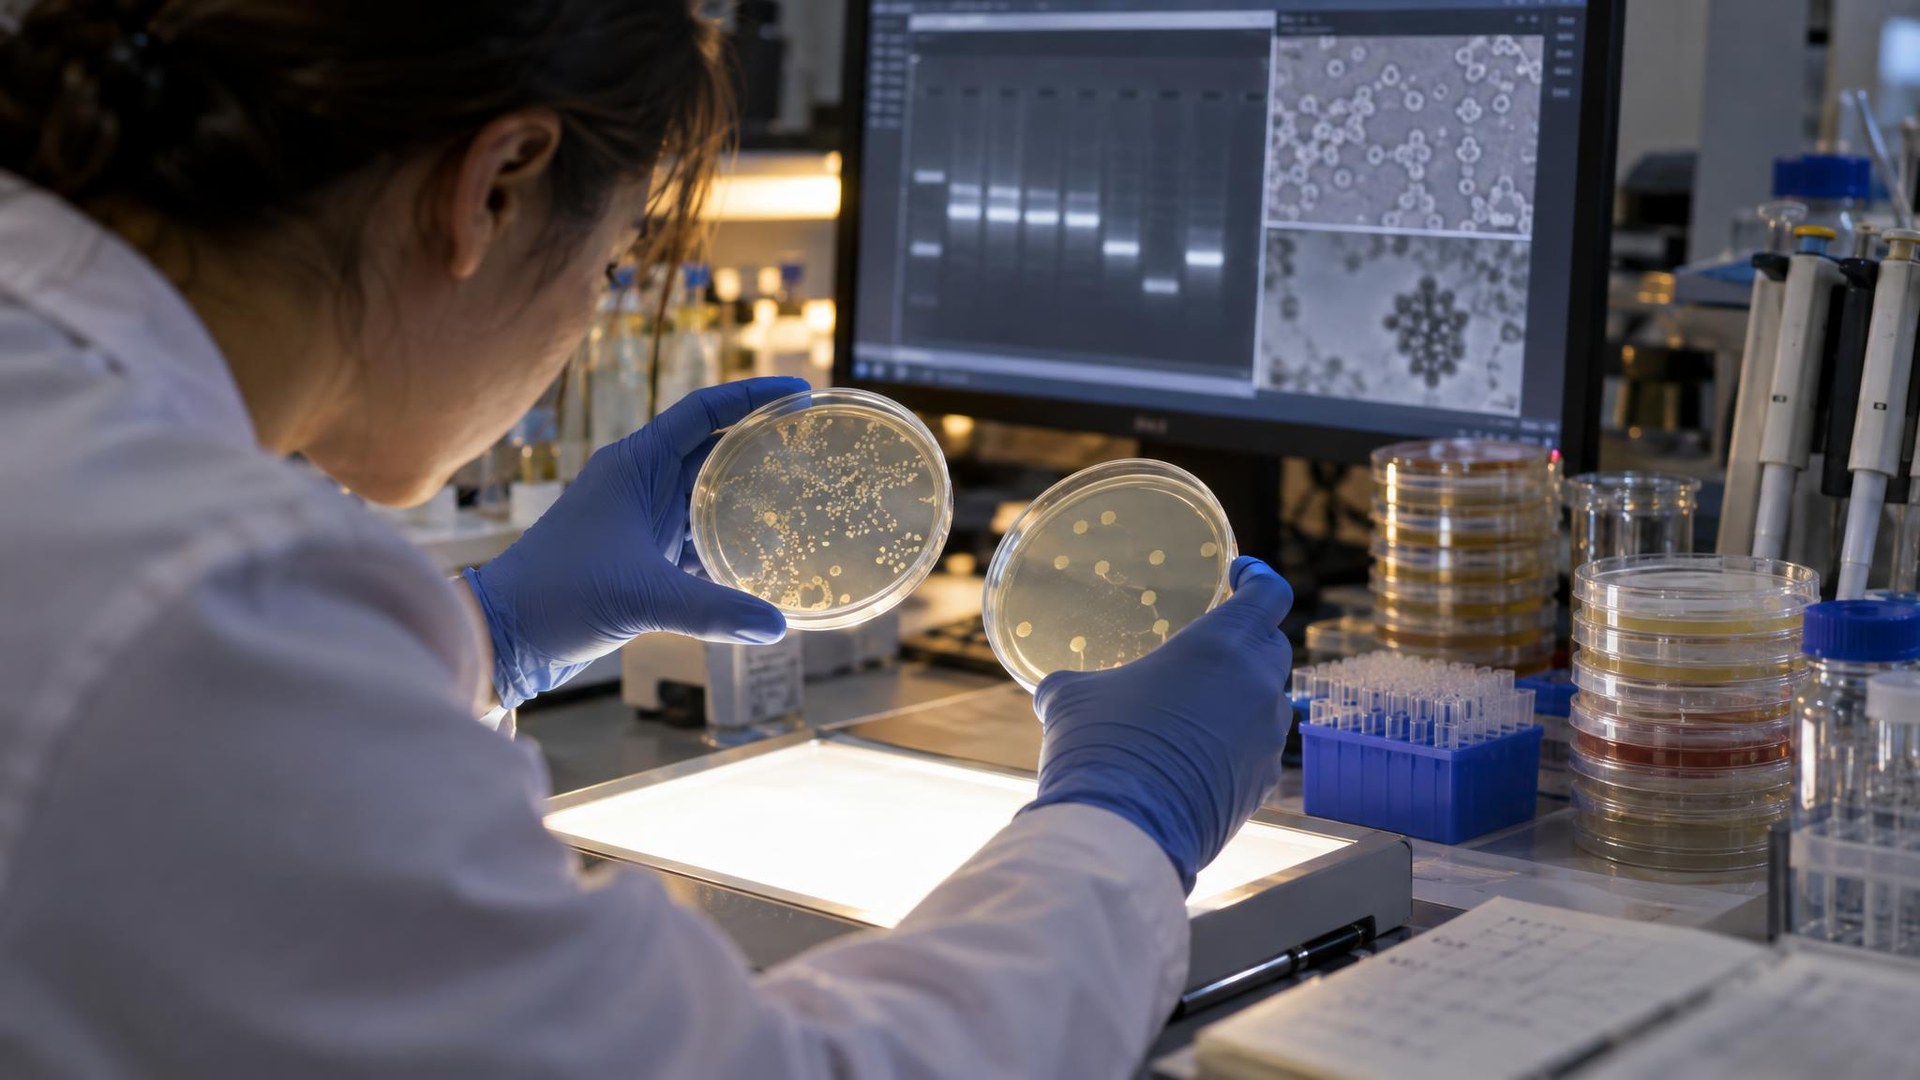
BioBasicsBench tests whether agents can read messy wet-lab evidence—gels, plates, microscopy and instrument files—rather than cleaned paper figures. OpenAI built it with enzyme-design firm Ligo and reports rubric mean reward across seven models. Astra’s edge shows up in catching dye interference and bad controls, but OpenAI also publishes failures such as wrong colony-PCR lane picks and overcounts. The benchmark is useful for biosafety tracking as lab agents improve. openai.com is blocked to our checker, so Unite.AI is the reachable press source; the OpenAI post remains the primary document readers should open if they can.
Key facts
- Announced Nov 6, 2026
- 100 tasks with Ligo
- GPT-6 Astra 66.7% at xhigh
- GPT-5.6 Sol 43.8% at xhigh
- Five domains of routine wet-lab work